
On September 23, 2026, Alibaba's Tongyi Qianwen officially released the Qwen‑Audio‑3.1 series of large speech models. This upgrade not only advances the three core models—automatic speech recognition (ASR), text‑to‑speech (TTS) and real‑time speech interaction (Realtime)—but also introduces the new audio creation model Qwen‑Audio‑3.1‑TTS‑Next and the audio understanding model Qwen‑Audio‑3.1‑ASR‑Next. The five new models debuted together, forming a complete audio capability stack covering "understanding—generation—interaction—creation." To further lower the entry barrier, prices across the Qwen‑Audio line have been substantially reduced: TTS by about 70%, Realtime by about 85%, and ASR by up to 95%.
Details and Core Capabilities
Qwen‑Audio‑3.1‑ASR focuses on stronger contextual understanding and transcription polishing. The model further enhances multilingual and dialect recognition, adding native transcription polishing that can automatically remove filler words and repeated expressions and reorganize semantics to make the output text smoother and more coherent. It supports end‑to‑end role‑based transcription, jointly outputting speaker labels, timestamps and text. A single model covers 30 languages and 16 Chinese dialects; streaming recognition first‑character response time is about 160 milliseconds. In tests on open‑source dialect datasets the average character error rate (CER) was 4.55%; on a proprietary Chinese dialect set the average CER was 10.38%; dialect‑to‑Mandarin average semantic sentence accuracy reached 82.10%.
Qwen‑Audio‑3.1‑ASR‑Next is a next‑generation architecture‑based audio understanding model that extends capabilities beyond "text in speech" to full audio information. It can recognize speaker emotion, environmental and mechanical sounds, and supports sound description, event localization, audio question‑answering and reasoning. For complex audio that includes dialogue, background music and environmental noise, the model can not only output dialog text but also describe the sound composition, the timing of events, and answer related questions.
Qwen‑Audio‑3.1‑TTS enhances natural cross‑language voice synthesis. It supports multilingual and dialectal synthesis, allowing a single voice timbre to be naturally transferred across languages. Users can control emotion, speaking rate and style via simple text instructions, for example "read in a sharp, commanding tone with an authoritative feel."
Qwen‑Audio‑3.1‑TTS‑Next targets audio creation, adopting an architecture that combines language models and diffusion methods to generate human voice, sound effects and background audio in one pass. It supports multi‑role voice cloning, fine‑grained timestamp control and 48kHz output, suitable for podcasts, audiobooks, film and game audio production.
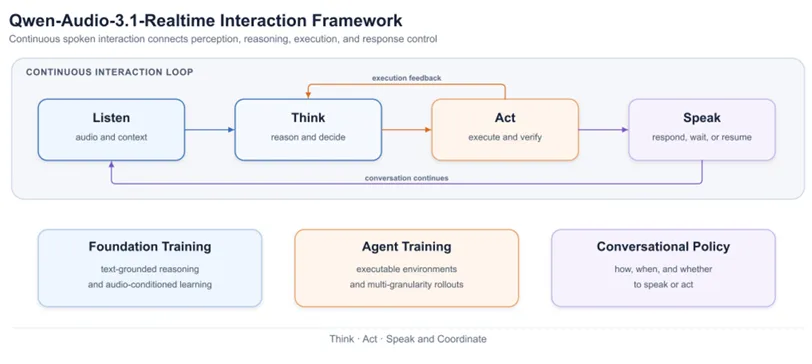
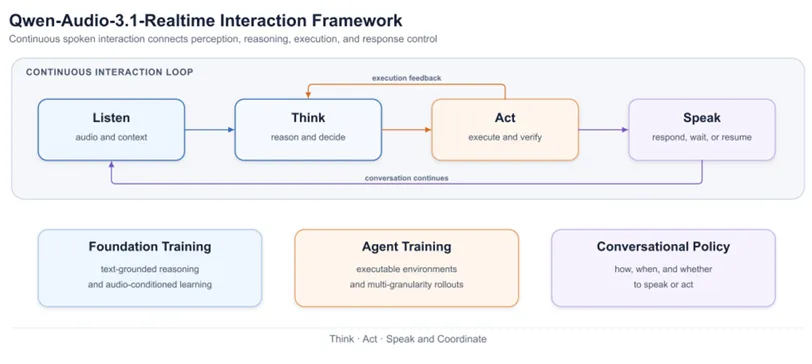
Qwen‑Audio‑3.1‑Realtime enables full‑duplex real‑time interaction, supporting speaking while listening and immediate interruption. The model uses a multi‑teacher distillation architecture, can perceive emotion and adjust response pacing (e.g., slowing and sounding more empathetic when detecting low mood), and supports multilingual real‑time switching and in‑dialogue tool calls. Some versions provide up to 262K context and support function calling and voice cloning.
Currently, ASR and Realtime models are already listed on the Qianwen AI platform (Alibaba Cloud Model Studio); ASR‑Next and TTS‑Next APIs will open soon. Some TTS‑related open‑source weights have also been released under the Apache 2.0 license.
Pricing Changes and Access
This round of price cuts is significant: TTS about 70% lower, Realtime about 85% lower, and ASR up to 95% lower. The steep reductions directly lower the adoption threshold for developers and enterprises, facilitating scaled deployment of voice capabilities in customer service, content creation, smart devices and agent scenarios.
Potential Impact
This release further completes Tongyi Qianwen's audio capability matrix, extending from traditional speech recognition and synthesis to environmental sound understanding, full soundscape creation and full‑duplex intelligent interaction, forming a more complete closed loop. For domestic developers, the deep price cuts and broad dialect support significantly improve accessibility, especially benefitting small teams and content creators seeking to deploy multi‑language and multi‑dialect applications quickly.
At the industry level, Qwen‑Audio‑3.1 competes directly with contemporaneous products such as Google's Gemini 3.8 Flash TTS, accelerating the evolution of speech foundation models from "usable" to "easy‑to‑use, affordable and creative." Enhanced real‑time interaction and emotion perception further promote voice as a natural interface for human‑computer interaction, and create synergy with Qianwen's office tools, Qoder and AI glasses hardware.
In the long term, the complete audio capability stack and aggressive pricing strategy may boost Tongyi's market share in the voice field and encourage more companies to elevate voice features from auxiliary tools to core interaction layers. At the same time, the real‑world performance in complex audio understanding and creation scenarios, as well as API stability and latency, will remain key factors for follow‑up validation.
Overall, by upgrading capabilities and cutting prices sharply, the Qwen‑Audio‑3.1 series both strengthens the technical stack and proactively reduces industry usage costs, marking a new stage in China's speech foundation models that emphasizes practicality and scaled deployment.
▶️ Enjoy this content? Creating takes a lot of work!
Subscribe to our YouTube channel:
AI Rosetta
Your likes, subscriptions and shares are our greatest support! 🙏
More AI news at: https://www.airosetta.com